GEO content (Generative Engine Optimization content) is web copy specifically structured, sourced, and formatted so AI search engines like ChatGPT, Google Gemini, and Perplexity extract and cite it in their generated answers. Unlike traditional SEO content written to rank a link on a page of search results, GEO content provides clear answer blocks, verifiable facts, and structured data that large language models (LLMs) parse during real-time web retrieval.
As of October 2026, standard search traffic patterns have shifted permanently toward answer engines. Old tactics like repeating focus keywords in subheadings or inflating word counts with broad intro paragraphs no longer work. Modern LLMs process content semantically using vector embeddings, preferring dense factual data over marketing prose.
For small businesses and growing agencies, scaling this style of writing manually presents a real operational bottleneck. Solutions like PulseRank automate this transition by building monthly content plans, researching AI sub-questions, and publishing citation-ready articles directly to platforms like WordPress and Shopify.
What is GEO content and how does it differ from traditional SEO content?
GEO content prioritizes direct factual answers, extractable tables, and clear entity relationships over keyword frequency and backlink quantity. While traditional SEO content aims to convince a web crawler to rank a URL in ten blue links, GEO content aims to convince an AI synthesizer to quote its specific claims.
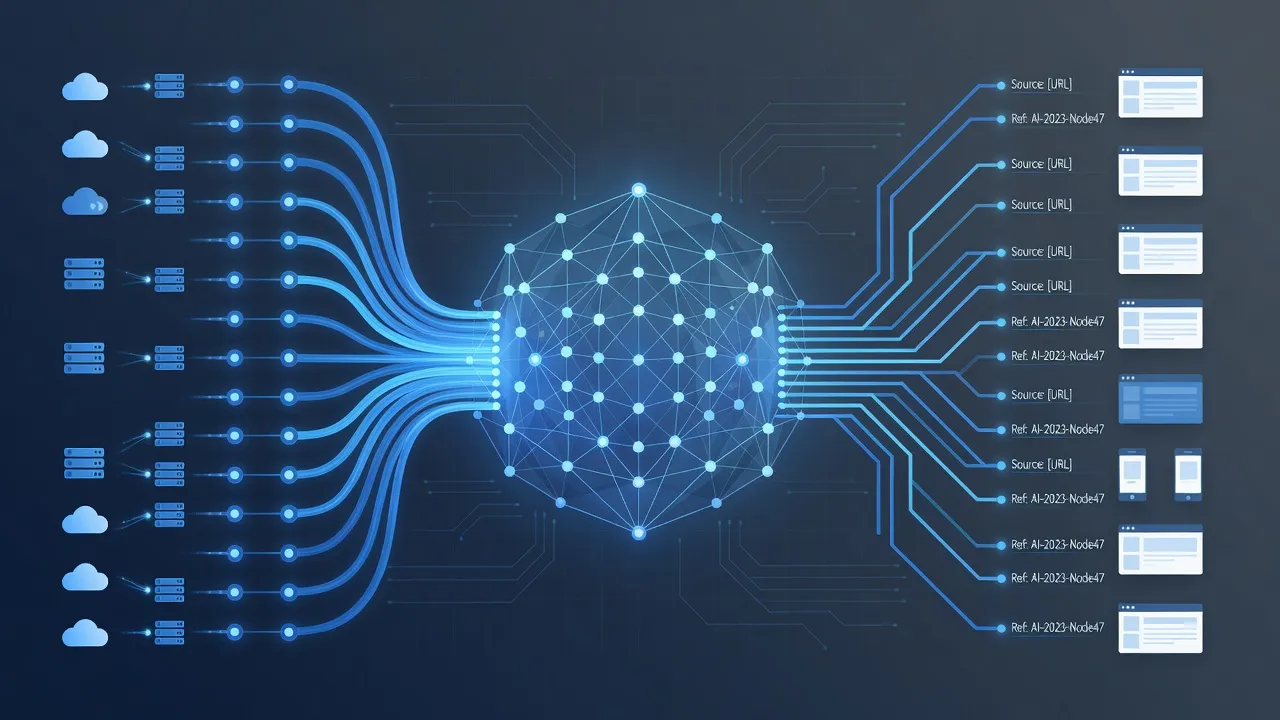
Traditional search engines index pages primarily based on keywords, link authority, and site structure. Generative engines run on neural retrieval models that break user queries into sub-questions, search the live web for matching text passages, and combine those excerpts into a unified response.
The shift changes how copy must be written:
- Information density: AI models ignore filler introductions and extract tight definitions.
- Data presentation: Tables and bullet lists are converted into structured context far more easily than dense paragraphs.
- Attribution requirements: LLMs require explicit source names, exact numbers, and dated statements to verify credibility before citing a page.
Understanding how to construct this material requires analyzing the top systems powering modern generative search. If you are auditing your current site visibility across these systems, reviewing a structured guide to GEO analysis helps benchmark your current brand citations.
How do companies get content cited by ChatGPT?
Companies get content cited by ChatGPT by structuring text into direct Q&A blocks, maintaining high information density, and ensuring web crawlers like GPTBot can access their pages. When ChatGPT executes a web search query, its underlying model retrieves real-time passages from top-ranking indexed pages and selects passages with high semantic similarity.
OpenAI relies heavily on clear topic organization. A page that starts every section with a direct, unambiguous answer sentence gives the model a clean chunk of text to extract.
To make your pages easy for ChatGPT to cite, focus on these specific requirements:
- Clear heading alignment: Match your subheadings directly to common search queries and follow them immediately with the answer.
- Third-party attribution: Include explicit references to reputable organizations, official documentation, or established research.
- Bot accessibility: Verify in your
robots.txtfile thatGPTBotandOAI-SearchBotare not blocked from crawling your core content sections.
User-agent: GPTBot
Allow: /

User-agent: OAI-SearchBot
Allow: /
According to official OpenAI documentation, search integration in ChatGPT relies on partner search engines alongside direct web crawling to present attributed sources directly within conversational UI threads.
How does content get cited by Google Gemini (SGE/Bard)?
Content gets cited by Google Gemini by matching entities in Google's Knowledge Graph and passing passage-ranking thresholds in Search index results. Gemini draws directly from Google's core search index, using AI Overviews to synthesize passages from pages that demonstrate high subject-matter expertise.
Google relies on established search infrastructure to select sources for Gemini. Pages that already rank in top organic positions have a structural advantage, but Gemini frequently pulls excerpts from lower-ranking pages if they contain precise data tables or clear definition blocks.
Key factors that drive Gemini citations include:
- Entity clarity: Clear noun relationships that help Google match your content against known entities.
- Schema implementation: Standardized JSON-LD markup that explicitly defines page attributes.
- Freshness signals: Explicitly dated statements, current figures, and updated timestamps.
As outlined in Google Search Central guidelines, adding structured data helps automated systems understand the explicit meaning of web pages, making it easier for automated features to surface content accurately.
GEO content vs traditional SEO content: key differences
The core difference between GEO content and traditional SEO content is that GEO content targets semantic extraction by AI models, whereas traditional SEO targets index ranking by search algorithms. The structural mechanics, evaluation metrics, and formatting requirements differ across both disciplines.
| Feature / Requirement | Traditional SEO Content | GEO Content (Generative Search) | PulseRank Automated GEO Workflow |
|---|---|---|---|
| Primary Goal | Rank link on page 1 of search results | Get cited as a source inside AI summaries | Generate citation-ready articles on autopilot |
| Writing Structure | Inverted pyramid with keyword placement | Direct Q&A blocks and extractable tables | Question-matched headers with immediate answers |
| Key Metric | Organic clicks and keyword rank positions | AI citation frequency and brand impressions | Search Console visibility and AI citation tracking |
| Content Focus | Comprehensive user coverage | Fact-dense chunks and semantic accuracy | Sub-question coverage with sourced citations |
| Data Formatting | Long-form prose with descriptive subheads | Concise lists, tables, and JSON-LD markup | Built-in tables, images, and schema architecture |
Managing these technical requirements across dozens of weekly publishing topics requires significant overhead. Platforms like PulseRank handle this by researching relevant sub-questions, generating structured articles, inserting relevant data tables, and publishing directly to your CMS for $499 per month.
Selecting the right generative engine optimization tools allows teams to standardize their editorial formatting without spending hours manually rebuilding every page layout.
What schema.org structured data helps content get cited by AI models?
Structured data types like Article, FAQPage, TechArticle, and Organization help AI models parse entity details and cite web content accurately. By implementing JSON-LD markup on your pages, you explicitly explain to machine readers what the page is about, who published it, and which facts are being asserted.
While AI models use advanced natural language processing to read HTML, structured code removes ambiguity. If an AI system needs to determine a pricing floor or product spec, JSON-LD provides an explicit data node.
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [{
    "@type": "Question",
    "name": "What is GEO content?",
    "answer": {
      "@type": "Answer",
      "text": "GEO content is web copy designed to be extracted and cited by generative AI search engines like ChatGPT and Gemini."
    }
  }]
}
The primary schema types used for generative visibility include:
- FAQPage: Formats explicit questions and direct answers for rapid passage extraction.
- Article / TechArticle: Defines the author, publishing entity, date published, and core subject matter.
- Organization: Establishes brand authority, social profiles, official websites, and official names.
- ClaimReview: Connects explicit factual statements with independent verification sources.
According to documentation on Schema.org, standardizing question-and-answer pairs within site code allows automated systems to digest site contents without relying solely on heuristic text extraction.
How does OpenAI choose sources to cite?
OpenAI chooses sources to cite by evaluating text relevance, source authority, passage clarity, and domain access permissions. When an answer requires live web retrieval, ChatGPT searches indexed web content to identify passages that directly resolve the user query.
The selection mechanism leans heavily on vector similarity search. The model converts the prompt into a mathematical embedding vector, then measures which web text passages sit closest to that request in semantic space.
The primary criteria OpenAI uses when selecting citations include:
- Semantic match: Does the text passage directly resolve the specific sub-question asked by the user?
- Information clarity: Is the statement direct and free from vague marketing filler?
- Source trust: Does the domain demonstrate consistent accuracy and subject authority?
- Crawl permission: Is the domain accessible to search crawlers without paywalls or restrictive blocking?
For teams looking to refine their optimization strategy, deploying specialized profound answer engine optimization techniques ensures content matches these neural retrieval patterns.
How are news publishers getting content cited by AI summarizers?
News publishers get cited by AI summarizers by producing fast factual updates, structuring articles with clear bullet points, and distributing content via structured feeds. News organizations represent high-trust nodes for AI systems seeking breaking information and real-time updates.
Generative summaries favor news stories that lead with core facts rather than narrative storytelling. The traditional inverted pyramid structure used in journalism works exceptionally well for AI extraction when paired with digital best practices.
Newsrooms adopt several tactics to secure visibility in AI summaries:
- Key takeaways callouts: Placing bulleted summaries right below the article headline for rapid extraction.
- Clear attribution tags: Citing primary source documents, press releases, or interviewees by name.
- Rapid syndication: Delivering clean XML and RSS feeds to platform indexing systems.
By separating hard facts from subjective editorial commentary, news sites increase the probability that an AI summarizer will pull their factual assertions directly into conversational answers.
What data licensing or syndication deals are publishers pursuing with AI companies?
Publishers are securing direct data licensing deals with AI companies to guarantee content inclusion in training sets and receive direct attribution in search summaries. Major digital media organizations recognize that web crawling alone does not protect their intellectual property or guarantee search placement.
Rather than relying purely on public web scraping, media conglomerates are negotiating multi-year commercial agreements. These partnerships provide AI developers with clean, structured access to archives in exchange for licensing fees and prominent citation placement.
Prominent examples of these licensing structures include:
- Financial Times & OpenAI: A strategic agreement allowing OpenAI to train models on FT material and cite its journalism directly in ChatGPT responses, as detailed in reporting by the Financial Times.
- Axel Springer & OpenAI: A multi-year partnership integrating coverage from Politico and Business Insider into OpenAI answer features.
- Reddit & Google: An enterprise data agreement granting Google real-time access to user discussions for model training and search integration.
For smaller businesses without enterprise legal teams, pursuing direct licensing deals is unnecessary. Creating well-structured GEO content remains the most effective path to securing visibility in generative search tools without custom API contracts.
How to structure GEO content for maximum AI citations
Structuring GEO content requires writing self-contained answer blocks, placing tables near key concepts, and maintaining a strict maximum of three sentences per paragraph. Every section on the page should read like an independent micro-article capable of answering a standalone question.
When an AI engine processes a page, it breaks the document down into discrete chunks. If a chunk depends heavily on context located three paragraphs earlier, the AI model may discard it as confusing or incomplete.
Follow this structural checklist when writing GEO content:
- Lead with the verdict: Put the direct answer in the first sentence beneath every heading.
- Use bold labels: Start bullet points with bold descriptive phrases to help parsers label entities.
- Add data tables: Convert multi-variable data into standard Markdown tables for clean parsing.
- Limit fluff: Remove introductory throat-clearing sentences that add no factual value.
Automating this structure across a full content schedule is often the hardest part for small teams. Using an all-in-one platform like PulseRank allows businesses to produce 30 citation-ready articles every 30 days, complete with keyword research, schema markup, images, and publishing automation for a predictable $499 monthly subscription.
Frequently Asked Questions
What is the difference between SEO and GEO content?
SEO content targets traditional search engine algorithms to rank web pages in blue link listings. GEO content targets generative AI engines like ChatGPT and Gemini to earn direct quotes and citations within synthesized answers.
Does schema markup help content get cited by ChatGPT?
Yes, schema markup like JSON-LD provides clean, structured entity data that helps machine readers understand facts and cite your pages accurately without relying on text heuristics.
How long should GEO content articles be?
Length depends on how many sub-questions the topic requires. Focus on information density and thorough answer blocks rather than meeting an arbitrary word count quota.
Why are data tables important for GEO content?
Data tables organize information into explicit rows and columns, allowing language models to lift structured specs, prices, and features easily into generated answers.
Can small businesses get cited by AI search engines without licensing deals?
Yes, small businesses earn AI citations by publishing structured, fact-dense content that directly answers search queries, uses clear schema markup, and maintains open web crawler access.
Is keyword stuffing effective for GEO content?
No, keyword stuffing harms GEO content visibility. Generative engines use semantic vector search to parse meaning, prioritizing clear factual explanations over repeated keywords.